Microsoft представила Echoverse: синтетические миры для обучения ИИ-агентов
Исследователи создали платформу глубоких симулированных сред для тренировки агентов, управляющих компьютером. Подход почти удваивает эффективность компактных моделей.
Суть
Исследовательское подразделение Microsoft представило Echoverse — платформу для обучения ИИ-агентов работе с компьютерными интерфейсами. Вместо того чтобы пытаться тренировать модели на реальных сайтах или статических скриншотах, ученые создали глубокие синтетические среды. Обучение в таких симуляциях позволило модели с 9 миллиардами параметров увеличить свою результативность с 36.5% до 67.1%, вплотную приблизившись к показателям более крупных систем.
Контекст
Обучение автономных агентов, способных работать с почтой, базами данных или системами поддержки клиентов, сталкивается с серьезной преградой. Реальные приложения постоянно меняются: обновляется дизайн, сдвигаются даты, а системы защиты блокируют автоматизированный трафик.
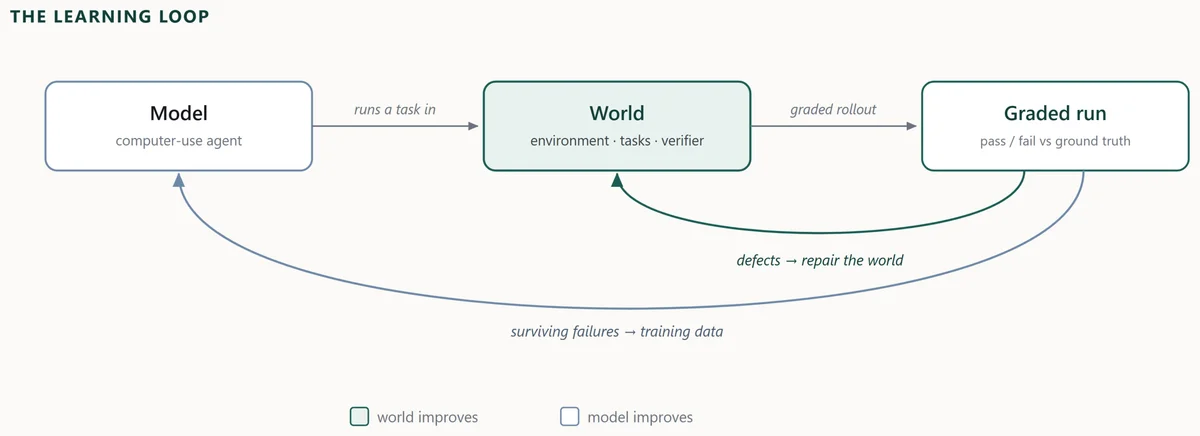
Circular diagram of the learning loop. A model runs a task in a world and every rollout is graded against database ground truth. Two arrows branch from the graded run: surviving failures flow to model training data, while defects flow to repairs of the environment, its tasks, and its verifier, so model and world improve on the same run.
Более того, действия в реальных системах имеют последствия. Если агент в процессе обучения нажмет не ту кнопку, он может отправить реальное письмо или удалить важные данные. Использование скриншотов решает проблему безопасности, но лишает модель понимания причинно-следственных связей. Агенту нужно видеть, как его действия меняют внутреннее состояние системы.
Детали
Команда Microsoft разработала двенадцать тренировочных миров: десять предметных сред, имитирующих реальные рабочие инструменты, и две среды для отработки конкретных навыков (например, работы со сложными календарями и фильтрами).
Ключевая особенность Echoverse — это «глубина» симуляции. Среда включает в себя не только пользовательский интерфейс (frontend), но и полноценную базу данных (backend). Когда агент совершает действие, система проверяет не изменение пикселей на экране, а фактическое изменение данных в базе.
Процесс обучения построен на совместной эволюции. Модель, сама среда и система проверки результатов развиваются одновременно. Когда агент сталкивается со сложной задачей и ошибается, эти ошибки становятся данными для дальнейшего обучения, а выявленные недостатки в симуляции оперативно исправляются.
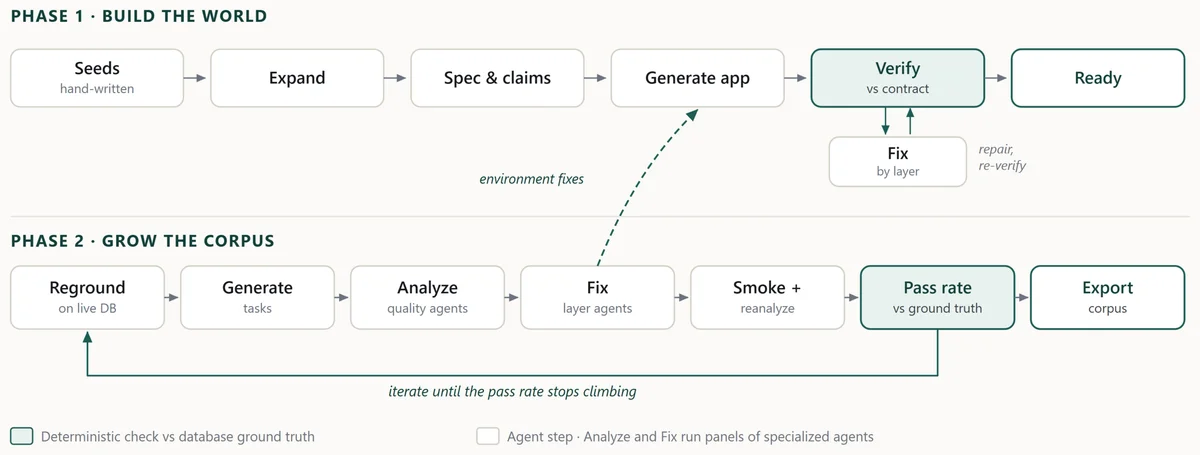
Two-phase pipeline diagram. Phase 1 expands seed scenarios into an app and repairs its database, backend, and frontend until it passes machine-checkable claims. Phase 2 regrounds tasks on live data and iterates a loop of analyzer and fixer agents, then re-scores against database ground truth until the pass rate plateaus. A dashed arrow shows many task-loop fixes landing back in the world.
Анализ
Эксперимент Microsoft доказал важный принцип: качество среды важнее её масштаба. Обучение на поверхностных копиях сайтов не просто бесполезно — оно ухудшает навыки агента. Системе необходимо понимать логику разрешений, сохранение состояния между экранами и зависимости в многошаговых рабочих процессах.
Внедрение обучения с подкреплением (reinforcement learning) внутри таких сред позволяет агентам выйти за рамки простого копирования человеческих действий. Получая точную обратную связь от базы данных, модель учится достигать цели за меньшее количество шагов и находит более оптимальные пути решения задач.
Перспектива
Microsoft открывает исходный код четырех из созданных миров, включая данные и системы оценки. Это важный шаг для всего исследовательского сообщества. Создание надежных ИИ-помощников для закрытых корпоративных систем невозможно без качественных полигонов для их тренировки. В будущем мы, вероятно, увидим появление целой индустрии, специализирующейся на создании сложных цифровых двойников корпоративного программного обеспечения специально для обучения искусственного интеллекта.
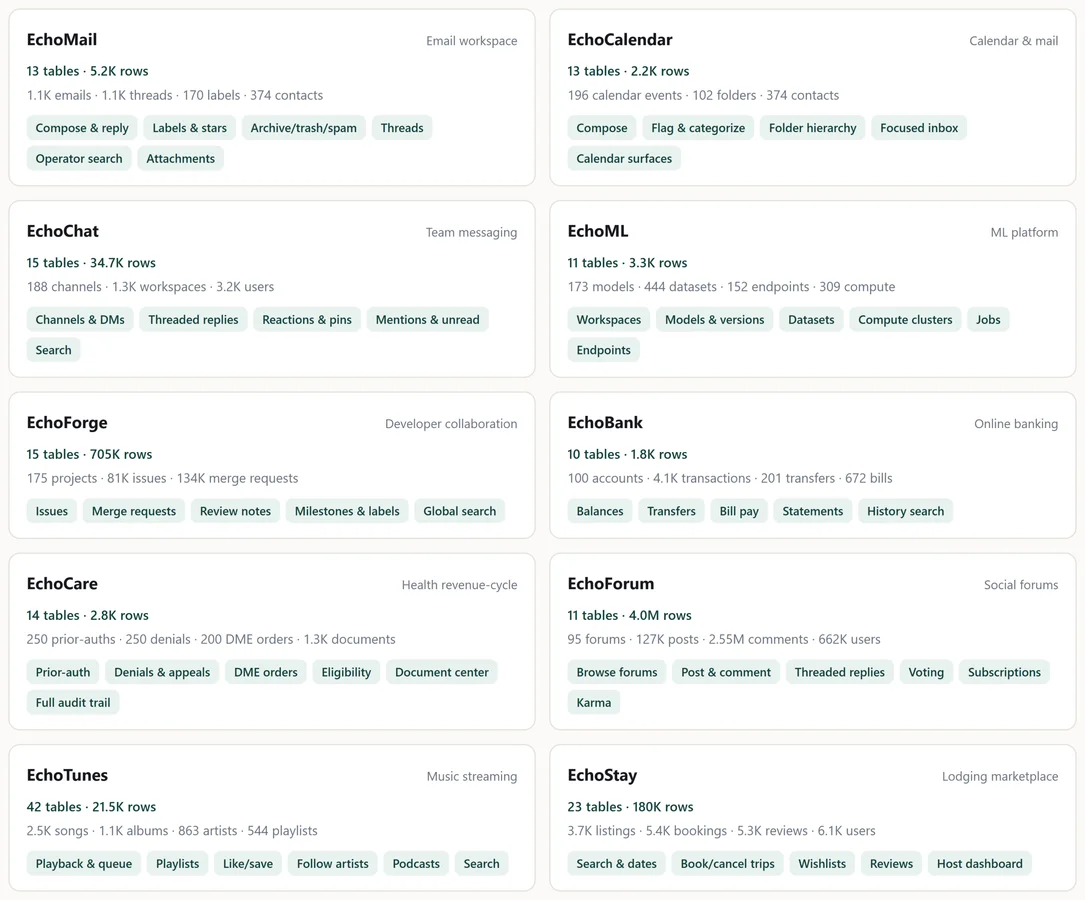
Grid of per-domain cards for the Echo suite. Each card names an environment and lists grounded database counts for its backend, seeded data, and feature surface, showing each is a self-contained interactive clone rather than a mockup.
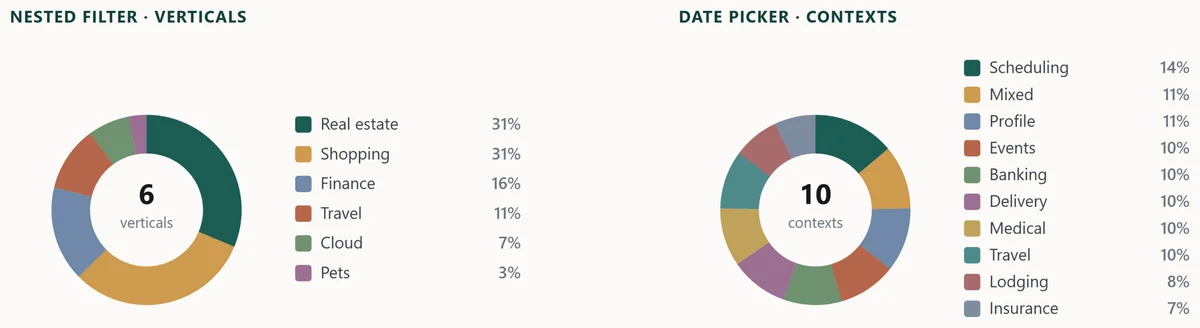
Diagram showing the capability controls re-themed across many domains: nested filters across six verticals and date pickers across ten everyday contexts, with the held-out sets reaching 36 further scenarios.
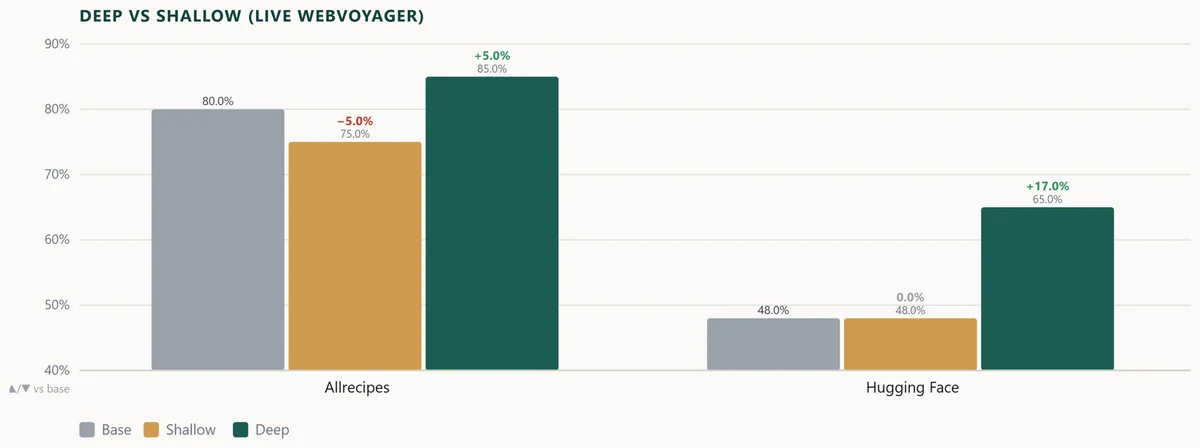
Grouped bar chart on two live WebVoyager domains, Allrecipes and Hugging Face, comparing base, shallow-world-trained, and deep-world-trained models. Shallow drops Allrecipes from 80.0% to 75.0% and leaves Hugging Face flat at 48.0%; the deep world lifts them to 85.0% and 65.0%.
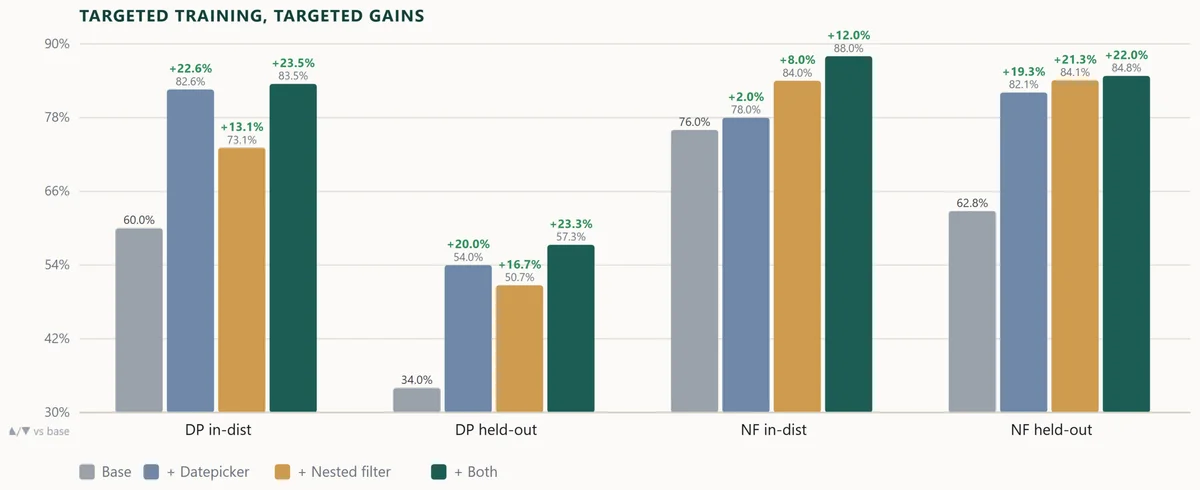
Grouped bar chart across four capability splits (datepicker in-distribution and held-out, nested-filter in-distribution and held-out) comparing base, plus-datepicker, plus-nested-filter, and plus-both models. Training either skill lifts both controls, and training both is the best all-rounder on every split.
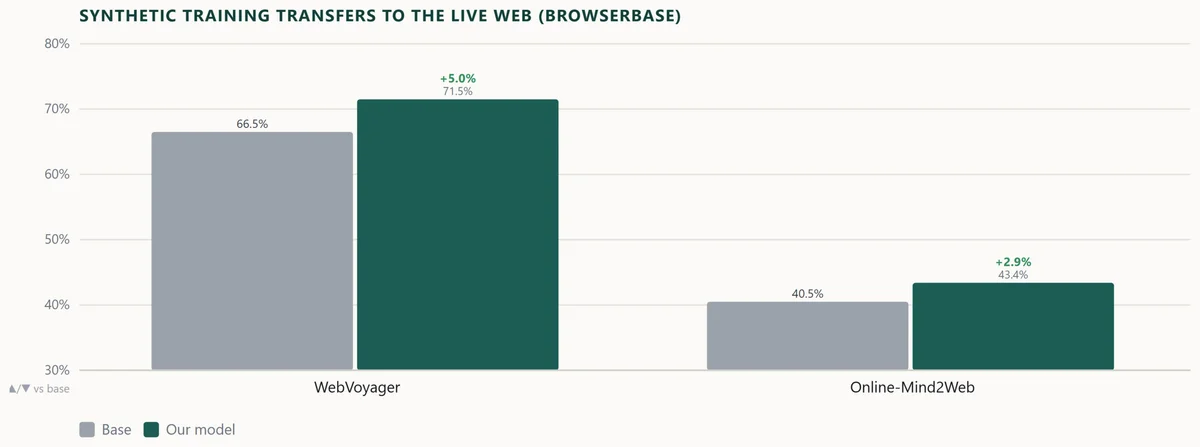
Bar chart on two live benchmarks scored through BrowserBase. The full-corpus model beats base on WebVoyager (66.5% to 71.5%) and Online-Mind2Web (40.5% to 43.4%), showing synthetic training transfers to sites it never trained on.
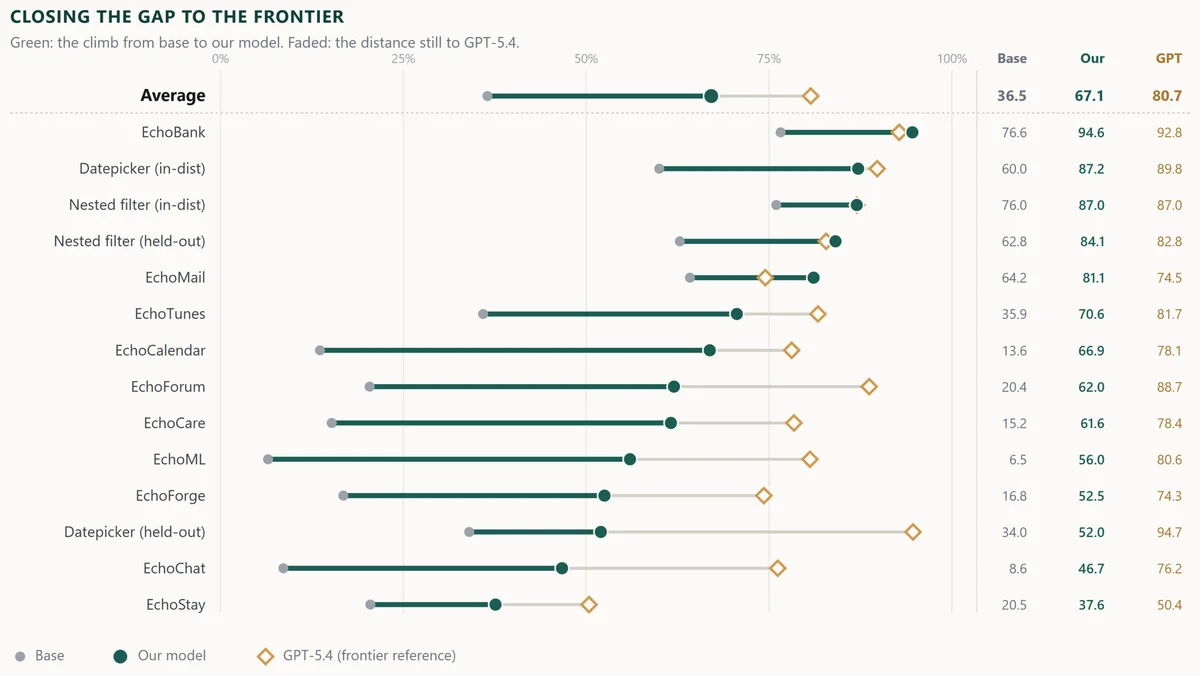
Dumbbell chart, per environment, of closing the gap to the frontier. For each of fourteen domains a grey dot marks base, a green dot our full-corpus model, and an amber diamond GPT-5.4; the green bar is the gain from base and the faded remainder is the distance still to GPT-5.4. A right-hand strip lists each model's exact Base, Our, and GPT score. Our model nearly doubles the base average to 67.1% and its green dot sits past the diamond on EchoBank and both nested filters, surpassing GPT-5.4.
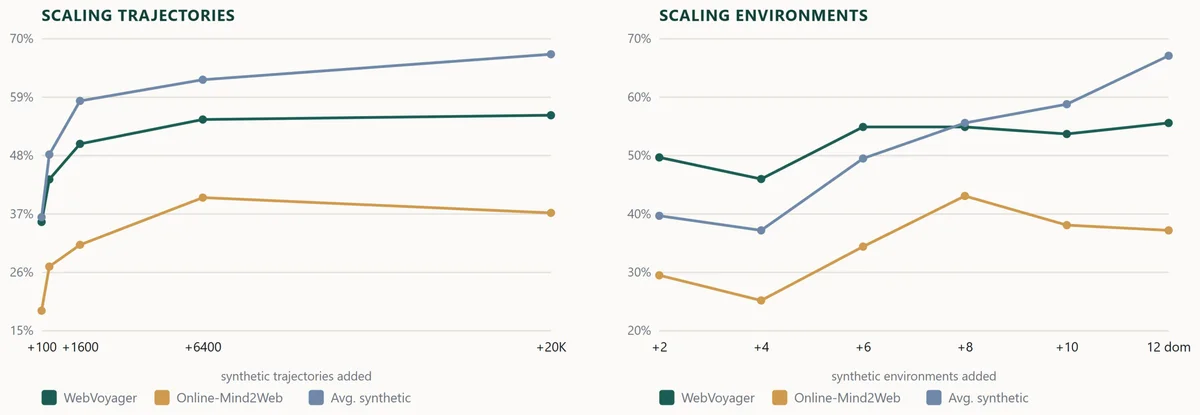
Two line charts of scaling, each plotting average synthetic score, WebVoyager, and Online-Mind2Web. Left, more trajectories through a fixed set of worlds, with the x-axis spaced by actual trajectory count so the points bunch at low counts and stretch out toward 20,000; the curves rise steeply then flatten, WebVoyager going flat and Online-Mind2Web slipping over the final stretch while the synthetic average climbs only gently. Right, more environments from two to twelve domains, where the synthetic average and WebVoyager keep climbing with breadth. The contrast shows that diversity of environments, not sheer trajectory volume, carries skill to unseen sites.
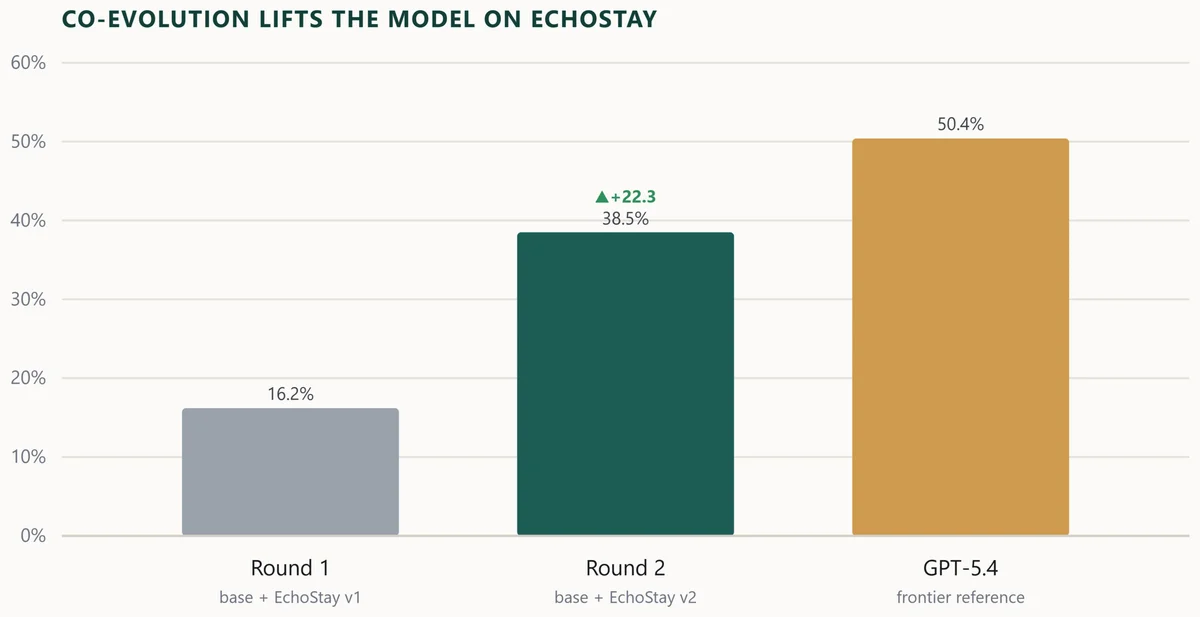
Bar chart of the model's score on EchoStay before and after one co-evolution round. As the world went from v1 to v2 the model more than doubled, from 16.2% to 38.5%, shown against GPT-5.4's 50.4% reference.
TL;DR
Главное
Для создания эффективных ИИ-агентов требуются глубокие синтетические симуляции рабочих программ, где действия модели оцениваются по изменениям в базе данных, а не по картинке на экране.
Ключевые факты
- /Создано 12 глубоких симулированных миров для обучения.
- /Результативность 9B модели выросла с 36.5% до 67.1%.
- /Обучение на поверхностных копиях сайтов приводит к деградации навыков ИИ.
- /Microsoft открыла исходный код четырех тренировочных сред.
Инсайт
Главным ограничением в развитии компьютерных агентов является не архитектура самих моделей, а отсутствие сред, способных адекватно реагировать на их действия и сохранять логику работы реальных приложений.